Python · Tkinter
Advanced Calculator
A GUI calculator with a full interface — basic operations, percentage, sign toggle, and error handling.
View code
Currently learning AI Engineering
AI Engineer in Progress
Computer Engineering Student | Building with Python, AI & Open Source
Learning, building, and evolving toward the world of Artificial Intelligence.
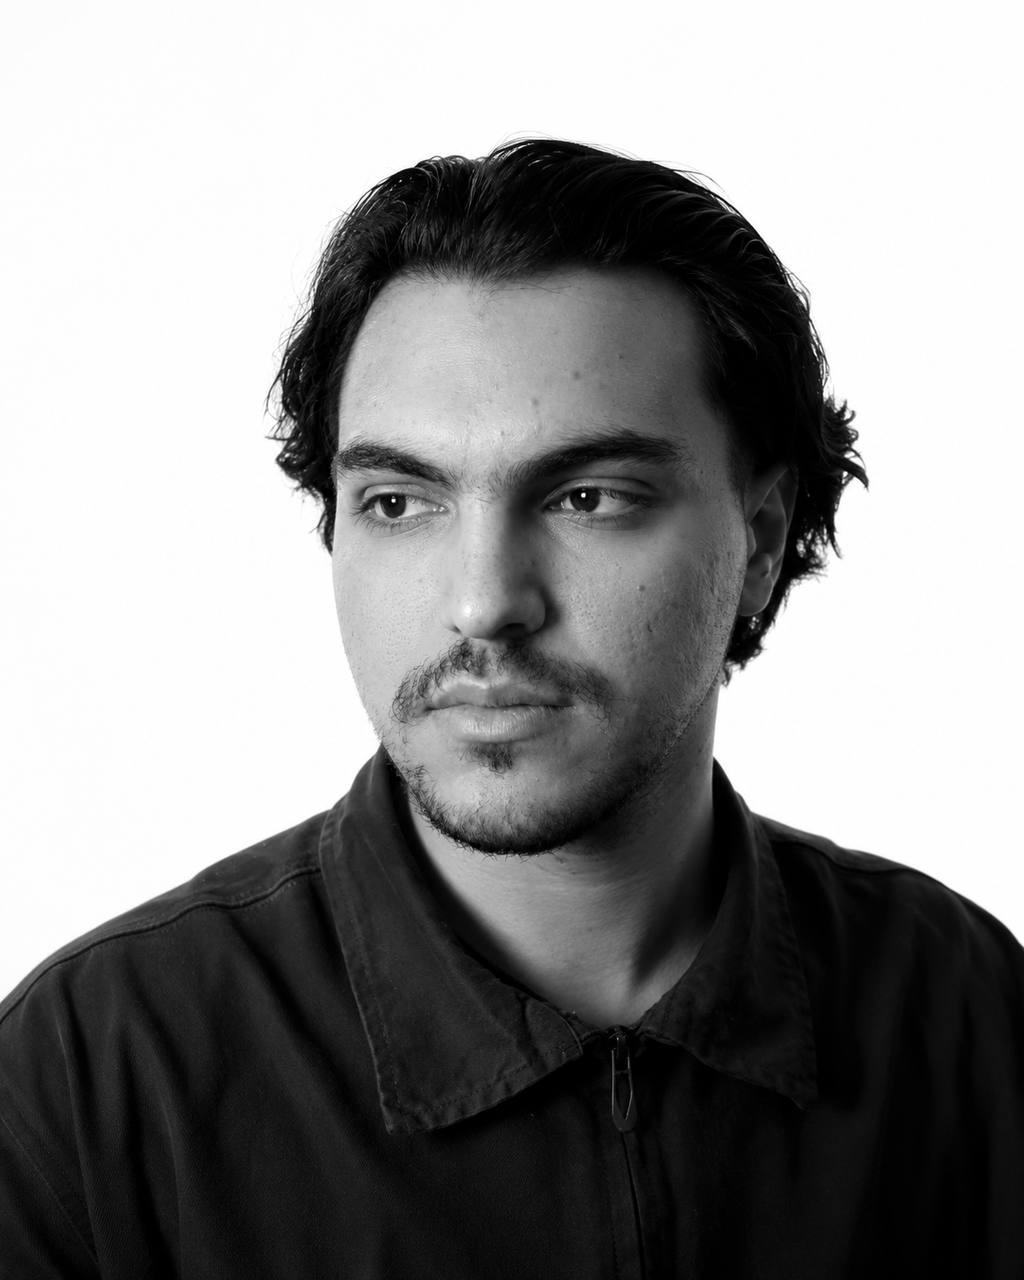
I'm a Computer Engineering student at Islamic Azad University, Najafabad, and my focus is moving steadily toward Artificial Intelligence.
I started with programming fundamentals, Java and the basics of the web. Now I'm working through Python, data analysis and machine learning, with deep learning, NLP and computer vision coming next.
I don't present myself as a finished engineer. This site shows the path, the skills I'm building and the things I make.
The path I'm following to become an AI Engineer — from foundations to engineering.
Starting point
Main deep learning framework
Skills I've built and paths I'm currently walking.
Building
Learning
Learning
Learning
Learning
Learning
Learning
Learning
Learning
Learning
Next
Next
Next
Next
Next
Next
Small things I've built while learning.
A GUI calculator with a full interface — basic operations, percentage, sign toggle, and error handling.
A daily task manager with add, delete, mark-as-done and file persistence.
Notes and small studies on things I'm learning.
A small study on how three classical models perform on imbalanced financial transactions.
Fraud detection is one of the classic problems in applied machine learning. Financial transactions are massive in volume, but only a tiny fraction of them are fraudulent — often less than 1%. This makes the problem highly imbalanced, and it means that a model that always predicts "not fraud" would still be correct 99% of the time. That is clearly useless, so we need better metrics and better models.
In this short study, we compare three models that are widely used in this domain: Logistic Regression, Random Forest, and XGBoost. The dataset is a standard credit card fraud dataset (284,807 transactions, 492 frauds).
Each one represents a different family of approaches:
Instead of training on the raw data, we use two common techniques:
We also use stratified k-fold cross-validation to make sure that each fold has the same proportion of frauds, and we evaluate with metrics that are appropriate for imbalance:
The table below shows the average performance of each model on the test set (5-fold cross-validation):
| Model | Precision | Recall | F1 | ROC-AUC | PR-AUC | Train time |
|---|---|---|---|---|---|---|
| Logistic Regression | 0.86 | 0.91 | 0.88 | 0.97 | 0.72 | ~2s |
| Random Forest | 0.93 | 0.89 | 0.91 | 0.98 | 0.81 | ~45s |
| XGBoost | 0.95 | 0.92 | 0.93 | 0.99 | 0.87 | ~30s |
XGBoost leads on F1, but the gap over Random Forest is small.
Fraud detection often cares about recall more than precision — missing a fraud is usually more expensive than a false alarm. But if recall is too high, the system flags too many legitimate transactions, which annoys customers.
XGBoost wins on both axes — but Random Forest is very close and much easier to tune.
If I had to pick one model to start with, I'd go with Logistic Regression as a baseline, then move to Random Forest if it's not enough, and only reach for XGBoost when I have time to tune it properly. In practice, the biggest gains usually come from better features and better data, not from a fancier model.
Click any certificate to view it larger.
I'm always interested in learning, collaborating and exploring new ideas in AI. If you have an idea or just want to say hi, I'd love to hear from you.